Fuzzy-Rough developments for Weka
Many of our developed fuzzy-rough feature selection measures and classifiers have been ported directly to the Weka Machine Learning Workbench. The standalone distribution contains all necessary dependencies and extended modules pre-configured for immediate execution.
Included Algorithms and Evaluators
The extended Weka tool encompasses evaluator metrics, search strategies, and classifiers designed specifically for hybrid rough and fuzzy-rough approaches.
Attribute Selection and Evaluators
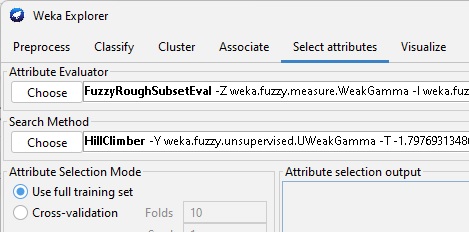
- FuzzyRoughSubsetEval: Incorporates various dependency and consistency measures, supporting customizable t-norms, implicators, and similarity metrics.
- HillClimber: Analogous to Greedy Stepwise search, but enhanced to support search to a degree α (for α-decision reducts) and non-monotonic metrics such as VQRS.
- AntSearch (ACO): Implements Ant Colony Optimization for minimal reduct discovery, with optional heuristic matrix pre-initialization.
- PSOSearch: Particle Swarm Optimization formulated for discrete binary feature subsets.
Classifiers and Statistical Testing
- Fuzzy-Rough Nearest Neighbours (FRNN): Instance-based classification weighting membership by lower and upper approximations.
- QuickRules: Rule induction algorithm extracting transparent rule sets.
-
Non-Parametric Statistical Tests: Directly integrated into the Weka Experimenter
environment, providing:
- Mann-Whitney U test
- Wilcoxon signed ranks test
- Friedman test with Holm's post-hoc procedure
Configuring Java Heap Memory
When executing feature selection on high-dimensional data or large sample sizes, increasing the allocated Java heap size is recommended. You can run the program using the helper launcher script:
Or launch directly from your terminal or command prompt:
java -Xmx4096m -jar weka.jar
Implementations Across Other Ecosystems
In addition to Weka, fuzzy-rough algorithms are available in multiple modern data science platforms:
Python Ecosystem
A scikit-learn compatible Python library providing fuzzy-rough classifiers, instance selection, and feature selection approaches.
View on PyPI →R Statistical Environment
Official CRAN package implementing classical rough sets and fuzzy-rough data analysis for R data frames and predictive pipelines.
View on CRAN →KEEL Platform
Knowledge Extraction based on Evolutionary Learning (KEEL) includes integrated fuzzy-rough algorithms for preprocessing and benchmarking.
Visit KEEL Portal →